
README file from
GithubLLM Token Count
Real LLM token counts for GLM, GPT, Qwen & DeepSeek in Obsidian's status bar — so you know if a note fits the context budget before you send it.


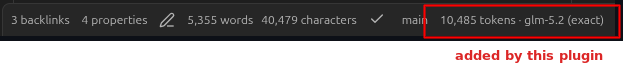
The token count appears in the status bar alongside Obsidian's built-in word and character counts — live, for whatever note you have open.
What it does
- See token counts before you send. The status bar shows the active note's token count under your chosen model's tokenizer, so you can tell at a glance whether it fits the context window or needs chunking/summarizing.
- Accurate for GLM-5.2 — not a GPT approximation. The only Obsidian token-count plugin that tokenizes GLM-5.2 with its real HuggingFace tokenizer. GPT-based counters over-count Chinese by 10–30%, which misleads your context-budget decisions if you actually run GLM.
- 11 models, honestly labeled. GLM, GPT, Qwen, and DeepSeek are exact; Claude and Gemini are approx (
o200k_base × 1.15, clearly labeled — never silently passed off as exact). - Offline after first use. The tokenizer is fetched once from HuggingFace and cached locally. Subsequent counts are instant and need no network. GPT/Claude/Gemini need no fetch at all.
Installation
- Download
main.js,manifest.json, andstyles.css. - Place them in your vault at
.obsidian/plugins/llm-token-count/. - In Obsidian: Settings → Community plugins, reload the plugin list, enable LLM Token Count.
On first use with a HuggingFace-sourced model (GLM, Qwen, DeepSeek), the plugin fetches the tokenizer and caches it locally. The first count takes a few seconds; every count after is instant.
Configuration
Open Settings → LLM Token Count:
- Default model — dropdown of all 11 supported models. Changing it re-counts the active note immediately.
- Re-download tokenizer — clears the cached tokenizer for the current model so the next count re-fetches from HuggingFace. Use after a tokenizer version bump or if the cache becomes corrupt.
Compatibility
- Obsidian 1.4.0+, desktop only. The plugin uses Node's
fsandfetchfor the tokenizer cache, which aren't available on mobile. - Coexists with other token-count plugins (TokenBar, Token Count, TikToken Tokenizer, LLM Token Counter). This plugin's differentiator is GLM support and multi-model exact counting via HuggingFace tokenizers.
- No data leaves your machine except the one-time HuggingFace tokenizer fetch. Notes are never sent anywhere — tokenization is fully local.
Supported models
| Model | Source | Mode |
|---|---|---|
glm-5.2, glm-5, glm-4.6v-flash |
HuggingFace tokenizer.json (pinned SHA) |
exact |
gpt-5, gpt-4o |
js-tiktoken o200k_base |
exact |
gpt-4, gpt-3.5 |
js-tiktoken cl100k_base |
exact |
qwen, deepseek-v3.1 |
HuggingFace tokenizer.json (pinned SHA) |
exact |
claude, gemini |
o200k_base × 1.15 |
approx |
GLM/Qwen/DeepSeek tokenizer SHAs are pinned to a specific HuggingFace commit for reproducible counts across machines and over time.
License
MIT